Skip to content
Tags
N₀-Foundation: Towards the Age of Tactile Intelligence

N₀-Foundation: Towards the Age of Tactile Intelligence

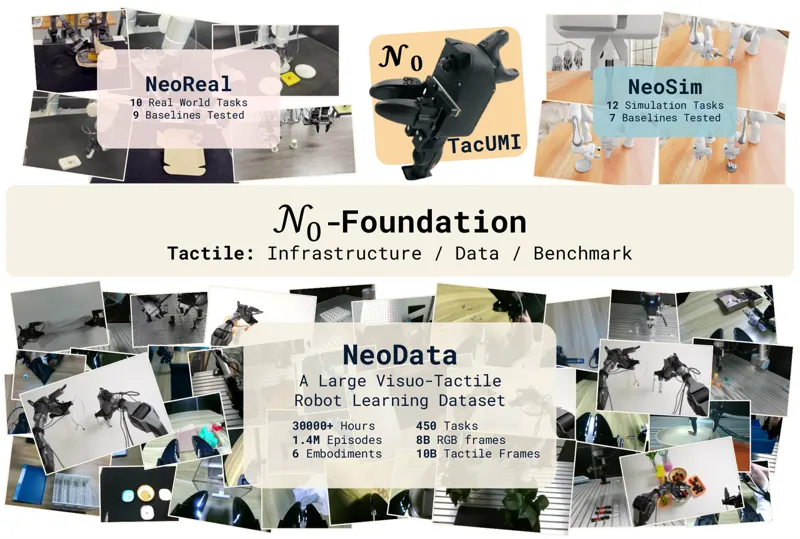
We present N₀-Foundation, a paradigm for tactile-enabled embodied manipulation, which integrates tactile sensing hardware, large-scale multimodal data, tactile representation learning, and standardized evaluation. First, we engineer the infrastructure for scalable data collection, including a vision-based tactile sensor, a tactile Universal Manipulation Interface (UMI), and a synchronized visuo-tactile data collection system supporting both robot embodiments and UMI-based demonstrations. Leveraging this infrastructure, we construct NeoData, which contains more than 30000 hours of synchronized visual and tactile demonstrations, spanning six embodiments, 450 tasks, and billions of paired RGB and tactile frames collected through a mixture of real-robot teleoperation and UMI-based demonstrations. To facilitate open research, we further release OpenNeoData, a 5000-hour open-source subset of NeoData. The dataset addresses a central limitation of existing manipulation corpora, critical for deformable-object manipulation, precise assembly, delicate force control, and sustained surface interaction. Capitalizing on the large-scale, heterogeneous tactile measurements, we propose NeoForce, a visuo-tactile representation model that learn transferable tactile representations across different sensor designs. To enable systematic evaluation of tactile embodied models built upon our infrastructure, datasets and tactile representations, we further propose a comprehensive benchmark, which combines the real-world NeoReal suite and the simulated NeoSim suite for standardized evaluation. Experiments across both suites show that policies benefit from the physical contact state rather than from the device-specific appearance of the tactile signal. We release the dataset, the representation, and the benchmark, aiming at supporting future work on tactile-enabled embodied manipulation.
NeoteAI Team, Fudan TEAI TeamAug 30, 2026
UMIVLATactile PerceptionAug 30, 2026
HiFi-UMI: Learning Deployable Manipulation Policies from High-Fidelity UMI Data Alone

HiFi-UMI: Learning Deployable Manipulation Policies from High-Fidelity UMI Data Alone

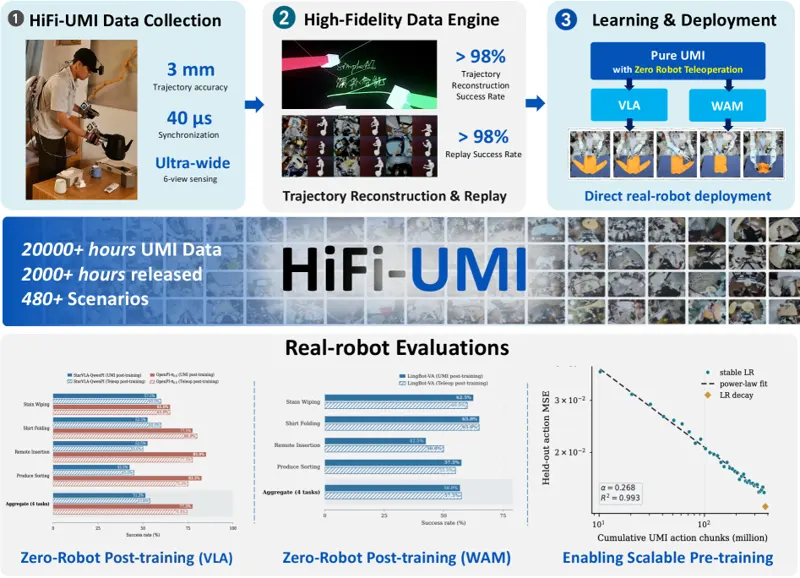
Learning deployable manipulation policies is bottlenecked by the scarcity of data that is both high-fidelity and scalable. Real-robot teleoperation is accurate but costly to scale; robot-free UMI capture scales readily, and current practice uses the resulting data mainly for pre-training, adding a small real-robot "anchor" at post-training. We ask whether raising the fidelity of robot-free UMI data, rather than shrinking the real-robot fraction, can remove that anchor. We present HiFi-UMI, a portable UMI data-production system co-designed for trajectory accuracy, inter-gripper relative pose, synchronization, and field of view: head-mounted offline stereo-inertial SLAM, native rather than reconstructed relative pose, a shared microsecond GPIO trigger, and two wide-angle cameras per hand covering ~200 degrees. It reaches 3 mm workspace-local end-effector accuracy without external tracking infrastructure. Using this corpus, we demonstrate zero-robot post-training: a policy post-trained solely on HiFi-UMI demonstrations deploys directly on a real robot and matches in-domain teleoperation across three backbones spanning the vision-language-action and world-action-model families, with success-rate differences of -2.5, +3.1, and -0.6 percentage points on StarVLA-QwenPI, OpenPI-pi_0.5, and LingBot-VA; the strongest policy reaches 85% on a precision insertion task, even though the teleoperation baseline is collected in the evaluation scene and no HiFi-UMI trajectory is. Pre-training on 4,000 hours from the same corpus lowers action error on ten unseen tasks by 41% and, on StarVLA-QwenPI, raises real-robot success by a further 18.1 percentage points. We open-source HiFi-UMI-2K, 2,000 hours of microsecond-synchronized, ultra-wide-FoV demonstrations, each automatically reconstructed and validated through simulation replay, as a large-scale, high-fidelity resource for the robot-learning community.

Simple AI, :, Yuteng WeiJul 28, 2026
UMIVLAHiFi-UMIJul 28, 2026