PAPER DEEP DIVE
Learning Humanoid Arm Motion via Centroidal Momentum Regularized Multi-Agent Reinforcement Learning
Humans naturally swing their arms during locomotion to regulate whole-body dynamics, reduce angular momentum, and help maintain balance. Inspired by this principle, we present a limb-level multi-agent reinforcement learning (RL) framework that enables coordinated whole-body control of humanoid robots through emergent arm motion. Our approach employs separate actor-critic structures for the arms and legs, trained with centralized critics but decentralized actors that share only base states and centroidal angular momentum (CAM) observations, allowing each agent to specialize in task-relevant behaviors through modular reward design. The arm agent guided by CAM tracking and damping rewards promotes arm motions that reduce overall angular momentum and vertical ground reaction moments, contributing to improved balance during locomotion or under external perturbations. Comparative studies with single-agent and alternative multi-agent baselines further validate the effectiveness of our approach. Finally, we deploy the learned policy on a humanoid platform, achieving robust performance across diverse locomotion tasks, including flat-ground walking, rough terrain traversal, and stair climbing.
Paper Metadata
Title: Learning Humanoid Arm Motion via Centroidal Momentum Regularized Multi-Agent Reinforcement Learning
Authors: Ho Jae Lee, Se Hwan Jeon, Sangbae Kim
Institution: MIT Department of Mechanical Engineering
Link: arxiv.org/abs/2507.04140
Video: youtu.be/uPC4OlujM3k
One-Sentence Summary
A limb-level multi-agent RL framework treating humanoid arms and legs as separate agents, using centroidal angular momentum (CAM) tracking and damping rewards to guide natural arm swing that reduces whole-body angular momentum and vertical ground reaction moments, validated on hardware for stable walking and vision-free stair climbing.
Background and Motivation
Humans naturally swing their arms during locomotion to regulate whole-body dynamics, reduce angular momentum, and maintain balance. Biomechanical studies show arm swing reduces leg-induced angular momentum, lowers ground reaction moments, and improves gait energy economy. However, for humanoid robots, how to effectively coordinate arm motion with locomotion remains unclear, especially with optimization or learning-based control.
Designing such controllers faces multiple challenges: whole-body dynamics complexity, locomotion task variability, and uncertainty in how arm motion should be guided. Imitation-based approaches match reference distributions but mimicking high-DoF trajectories doesn't necessarily align with platform-specific robustness. RL methods face conflicting rewards when planning arm and leg motions simultaneously; arm motion is often regularized with heuristics lacking physical basis. Model-based methods (full-body MPC) produce physically consistent arm motion but are computationally expensive for online closed-loop operation.
The key inspiration comes from biological evidence: arms and legs are not jointly planned at the cortical level—they originate from separate cortical areas, coupled only for stabilization in the cerebellum. This control separation offers engineering advantages: complex system optimization can be accelerated by "sectioning" physics. Inspired by this, the authors treat arm-leg coordination as a multi-agent RL problem—arms and legs as separate agents coupled only through centroidal dynamics.
Preliminaries
Centroidal dynamics describes linear and angular momentum around the CoM. CLM rate: $\dot{\mathbf{l}}_G = m\ddot{\mathbf{r}} = \sum_j \mathbf{F}_j + m\mathbf{g}$. CAM rate: $\dot{\mathbf{k}}_G = \sum_j (\mathbf{c}_j - \mathbf{r}) \times \mathbf{F}_j + \boldsymbol{\tau}_j$. Centroidal momentum compactly: $\mathbf{h}_G(\mathbf{q}, \dot{\mathbf{q}}) = \mathbf{A}_G(\mathbf{q})\dot{\mathbf{q}}$, where $\mathbf{A}_G$ is the centroidal momentum matrix (CMM). Generalized velocity decomposes into base, legs, and arms: $\dot{\mathbf{q}} = [\boldsymbol{\omega}_\mathcal{B}^\top, \boldsymbol{v}_\mathcal{B}^\top, \dot{\mathbf{q}}_{\text{legs}}^\top, \dot{\mathbf{q}}_{\text{arms}}^\top]^\top$.
CTDE (Centralized Training, Decentralized Execution): each agent maintains its own actor using local observations; critics access global information during training. Centralized critics stabilize training by making the environment stationary. The paper uses MAPPO.
Methods
Centroidal Momentum Modeling
Platform: 24.89kg humanoid, arms 5.71kg (22.8%), 10 leg joints, 8 arm joints. Pinocchio computes CMM; CasADi generates symbolic expressions; CuPySA parallelizes for batched evaluation. Total momentum decomposed: $\mathbf{h}_G = \mathbf{h}_{G,\text{base}} + \mathbf{h}_{G,\text{legs}} + \mathbf{h}_{G,\text{arms}}$. Reference momentum: $\hat{\mathbf{h}}_G(\mathbf{q}, \hat{\dot{\mathbf{q}}}) = \mathbf{A}_G(\mathbf{q})\hat{\dot{\mathbf{q}}}$, where $\hat{\dot{\mathbf{q}}}$ embeds user velocity command.
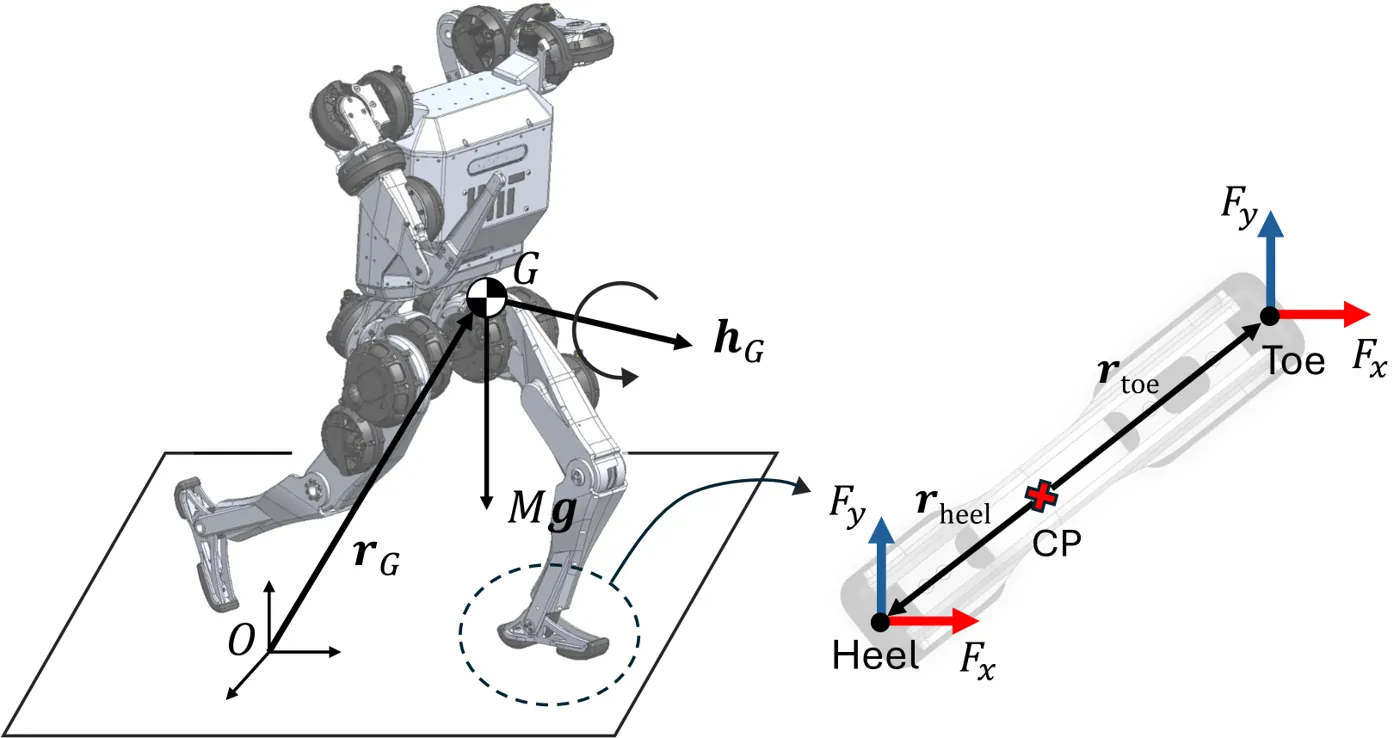
Figure 3: Left: Humanoid platform with centroidal momentum at CoM. Right: Foot top-down view with cylindrical collision primitive.
Arm Agent
Arms act as momentum generators regulating CAM. Observation $\mathcal{O}_{\text{arm}} \in \mathbb{R}^{41}$ includes base states, arm joint positions/velocities, previous action, and current/target CAM. Critic receives global info. Action $\mathcal{A}_{\text{arm}} \in \mathbb{R}^{8}$: residual arm joint commands.
CAM tracking reward encourages anti-phase arm swing:
$$r_{\text{CAM}} = \exp\left(-\left(\frac{\hat{\mathbf{k}}_G^z - \mathbf{k}_G^z}{1 + |\hat{\mathbf{k}}_G^z|}\right)^2 / \sigma\right)$$
CAM damping reward penalizes horizontal momentum build-up:
$$r_{\text{dCAM}} = -\min\left(0, \sum_{i \in \{x,y\}} \mathbf{k}_G^i \cdot \dot{\mathbf{k}}_G^i\right)$$
When horizontal CAM grows ($\mathbf{k}_G^i \cdot \dot{\mathbf{k}}_G^i > 0$), the penalty activates, encouraging arms to generate counter-momentum.
Leg Agent
Tracks velocity commands and contact frequency. Observation $\mathcal{O}_{\text{leg}} \in \mathbb{R}^{49}$ includes velocity command, contact phase, leg joint states, and shared base/CAM observations. Velocity tracking: $r_{vt} = \exp(-(\frac{\hat{\boldsymbol{v}}_\mathcal{B} - \tilde{\boldsymbol{v}}_\mathcal{B}}{1 + |\hat{\boldsymbol{v}}_\mathcal{B}|})^2 / \sigma)$. Contact schedule: $r_{cs} = (\mathbb{I}_{\text{r,contact}} - \mathbb{I}_{\text{l,contact}})\phi_{\text{contact}}$.
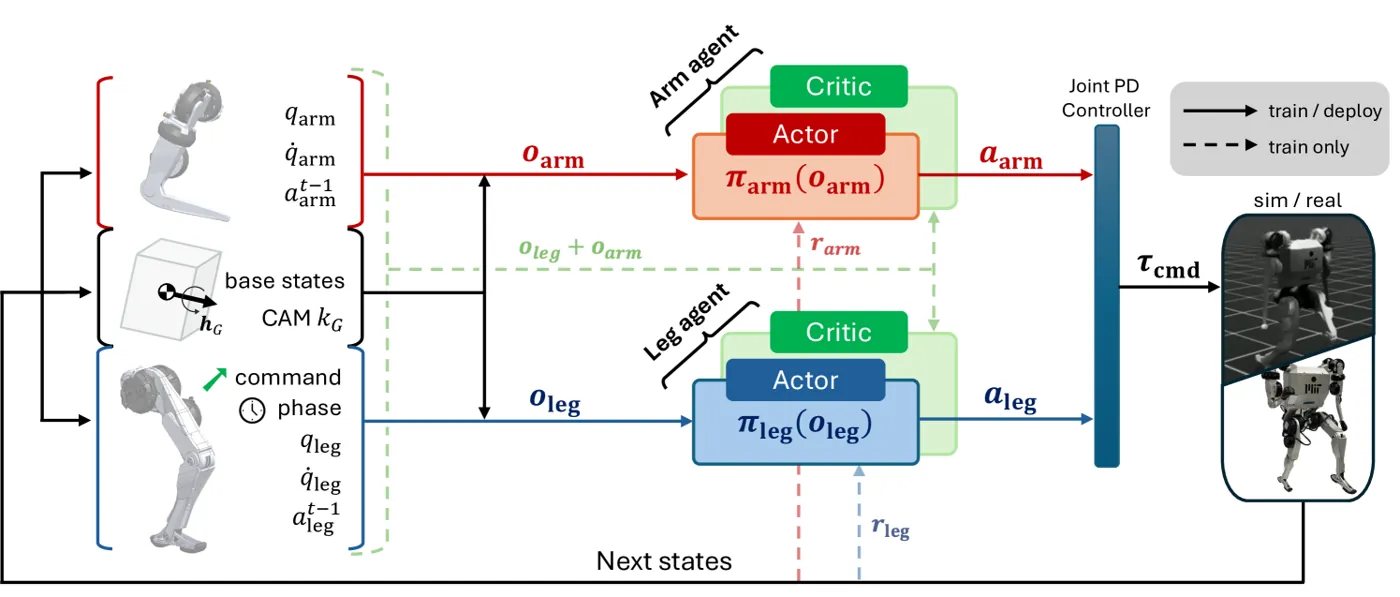
Figure 2: Limb-level multi-agent RL framework with separate actor-critic policies coupled through CAM.
System Pipeline
flowchart TB
    A[User Velocity Command] --> B[Reference CAM Computation]
    B --> C[Arm Agent
CAM Tracking + Damping]
    A --> D[Leg Agent
Velocity Tracking + Contact Schedule]
    C --> E[Arm Joint Actions
8 DoF residual]
    D --> F[Leg Joint Actions
10 DoF residual]
    E --> G[Joint PD Controller
1 kHz]
    F --> G
    G --> H[Humanoid Robot
24.89 kg, 18 DoF]
    H --> I[Centroidal Momentum
via Pinocchio/CuPySA]
    I --> C
    I --> D
    H --> C
    H --> D
Experimental Results
CAM Tracking
Figure 4 shows the method (With Arms) tracks vertical CAM more closely than Fixed Arms baseline. Decomposition reveals arm and leg angular momentum effectively cancel—leg swing produces positive momentum countered by arm anti-phase swing, improving total CAM tracking. This physically validates the biomechanical finding that arm swing reduces whole-body angular momentum.
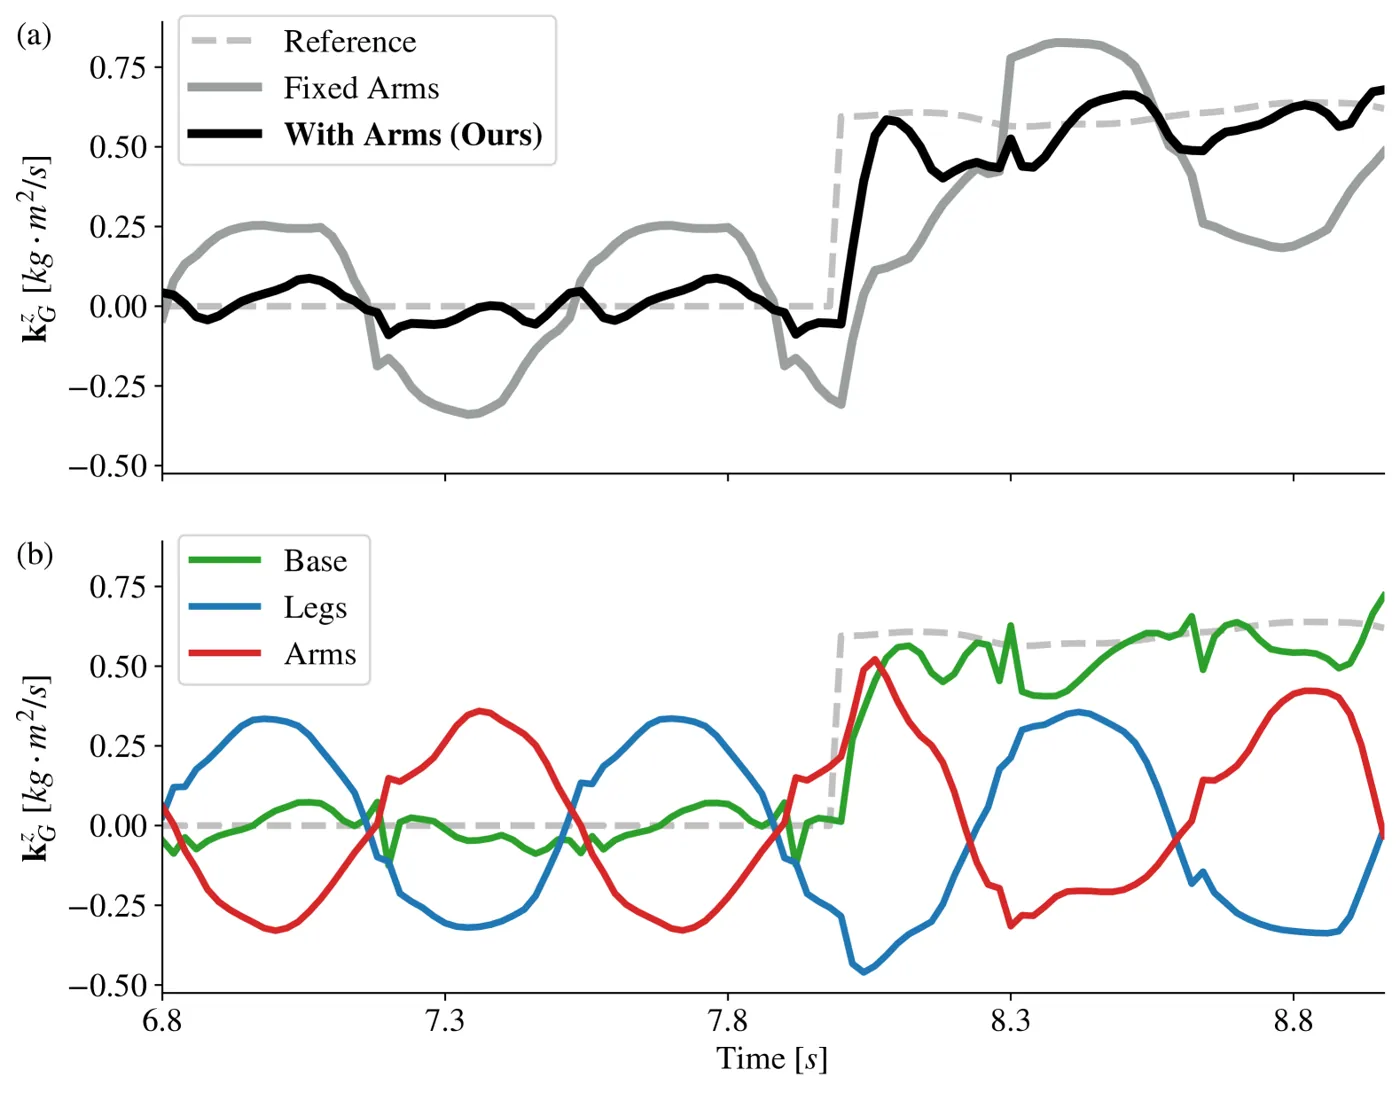
Figure 4: (a) Vertical CAM comparison; (b) CAM decomposition into base, legs, arms contributions
Vertical GRM Analysis
The method achieves narrower GRM distribution and lowest peak (Figure 5), consistent with Collins et al. Passive arm swing without CAM reward (With Arms w/o CAM) produces higher GRM peaks—uncontrolled arm motion negatively impacts stability. Arms must be consciously guided to aid balance.
| Method | GRM Peak | GRM Width | CAM Tracking | Recovery |
|---|---|---|---|---|
| Fixed Arms | High | Wide | Poor | Poor |
| With Arms w/o CAM | Highest | Widest | Poor | Medium |
| Ours (CAM-regularized MARL) | Lowest | Narrowest | Good | Good |
CTDE vs DTDE
CTDE achieves lower advantage function variance and faster convergence than DTDE (Figure 9). Low variance means more stable policy gradient estimates. Centralized actors introduce unnecessary input noise; optimal configuration is decentralized actors + centralized critics.
| Architecture | Actor Obs | Critic Obs | Adv. Variance | Convergence |
|---|---|---|---|---|
| Single-agent | Full | Full | High | Slow |
| Multi-agent DTDE | Local | Local | High | Slow |
| CTDE (centralized actor) | Full | Full | Medium | Medium |
| Ours CTDE (decentralized actor) | Local | Full | Low | Fast |
Hardware Experiments
Policy successfully transferred to hardware. Flat-ground walking shows clear anti-phase arm swing at 1.3 m/s. Vision-free stair climbing uses adaptive arm motion to recover from missteps and maintain balance. Training environments extended from flat terrain to rough surfaces, stairs, and inclines—emergent whole-body motion generalizes without modification.
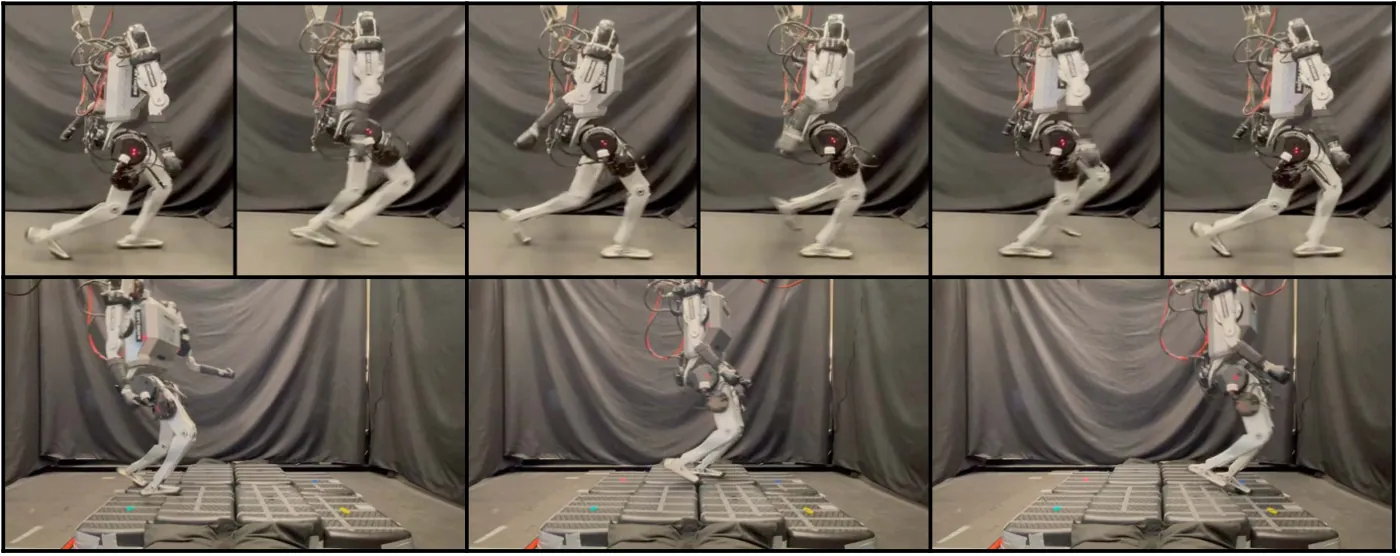
Figure 10: Hardware demos. Top: flat walking with anti-phase arm swing (1.3 m/s). Bottom: vision-free stair climbing with adaptive arm recovery.
Discussion
The core insight: arm-leg coordination doesn't need explicit joint planning—implicit coupling through shared CAM suffices. CAM as a compact representation of whole-body dynamics captures all dynamic interactions between arms and legs. This design simplifies training (each agent focuses on its own observations/rewards) and improves interpretability (CAM decomposition shows each limb's contribution).
Applicability boundary: CAM tracking assumes reducing angular momentum always benefits balance—valid for most walking but may need adjustment for tasks requiring active momentum generation (turning, sidestepping). Multi-agent framework assumes arm/leg task separability—when arms perform manipulation, additional task rewards may conflict with CAM rewards.
质心动量定理
$$ \dot{\mathbf{l}}_{G}=m\ddot{\mathbf{r}}=\sum_{j}\mathbf{F}_{j}+m\mathbf{g} $$
质心角动量定理
$$ \dot{\mathbf{k}}_{G}=\sum_{j}(\mathbf{c}_{j}-\mathbf{r})\times\mathbf{F}_{j}+\boldsymbol{\tau}_{j} $$
质心动量与关节速度的关系
$$ \mathbf{h}_{G}(\mathbf{q},\dot{\mathbf{q}})=\mathbf{A}_{G}(\mathbf{q})\dot{\mathbf{q}} $$
LimitationsAuthor-stated: Current validation limited to walking, rough terrain, and stairs. Future: more dynamic/contact-intensive scenarios (one-foot balancing, running, dribbling, kicking). Plans to combine with human motion datasets for enhanced naturalness.
Analysis: CAM damping formula only activates when momentum grows, potentially over-suppressing in scenarios needing active momentum (fast turning). Reference CAM computed from velocity commands via CMM projection—whether this reference is appropriate on all terrains needs validation. Training uses 4096 parallel environments (high compute). Hardware stair climbing is "vision-free"—arms operate on proprioception and CAM only, may need perception for complex stairs.
Conclusion
This paper presents a CAM-regularized multi-agent RL framework for learning natural humanoid arm swing and coordinated locomotion. Core contributions: biomechanically-motivated CAM tracking/damping rewards; limb-level CTDE architecture enabling independent training with implicit CAM coupling; experimental validation showing CAM-driven arm motion reduces vertical GRM and improves disturbance recovery. CTDE outperforms single-agent and DTDE baselines in advantage variance and convergence. Hardware deployment achieves stable walking (1.3 m/s), rough terrain traversal, and stair climbing with coordinated whole-body motion.
SOURCE LINKS